Featured
Intermediate
AI & Innovation
AI Model Quantization Explained: How Smaller Models Run on Less Hardware
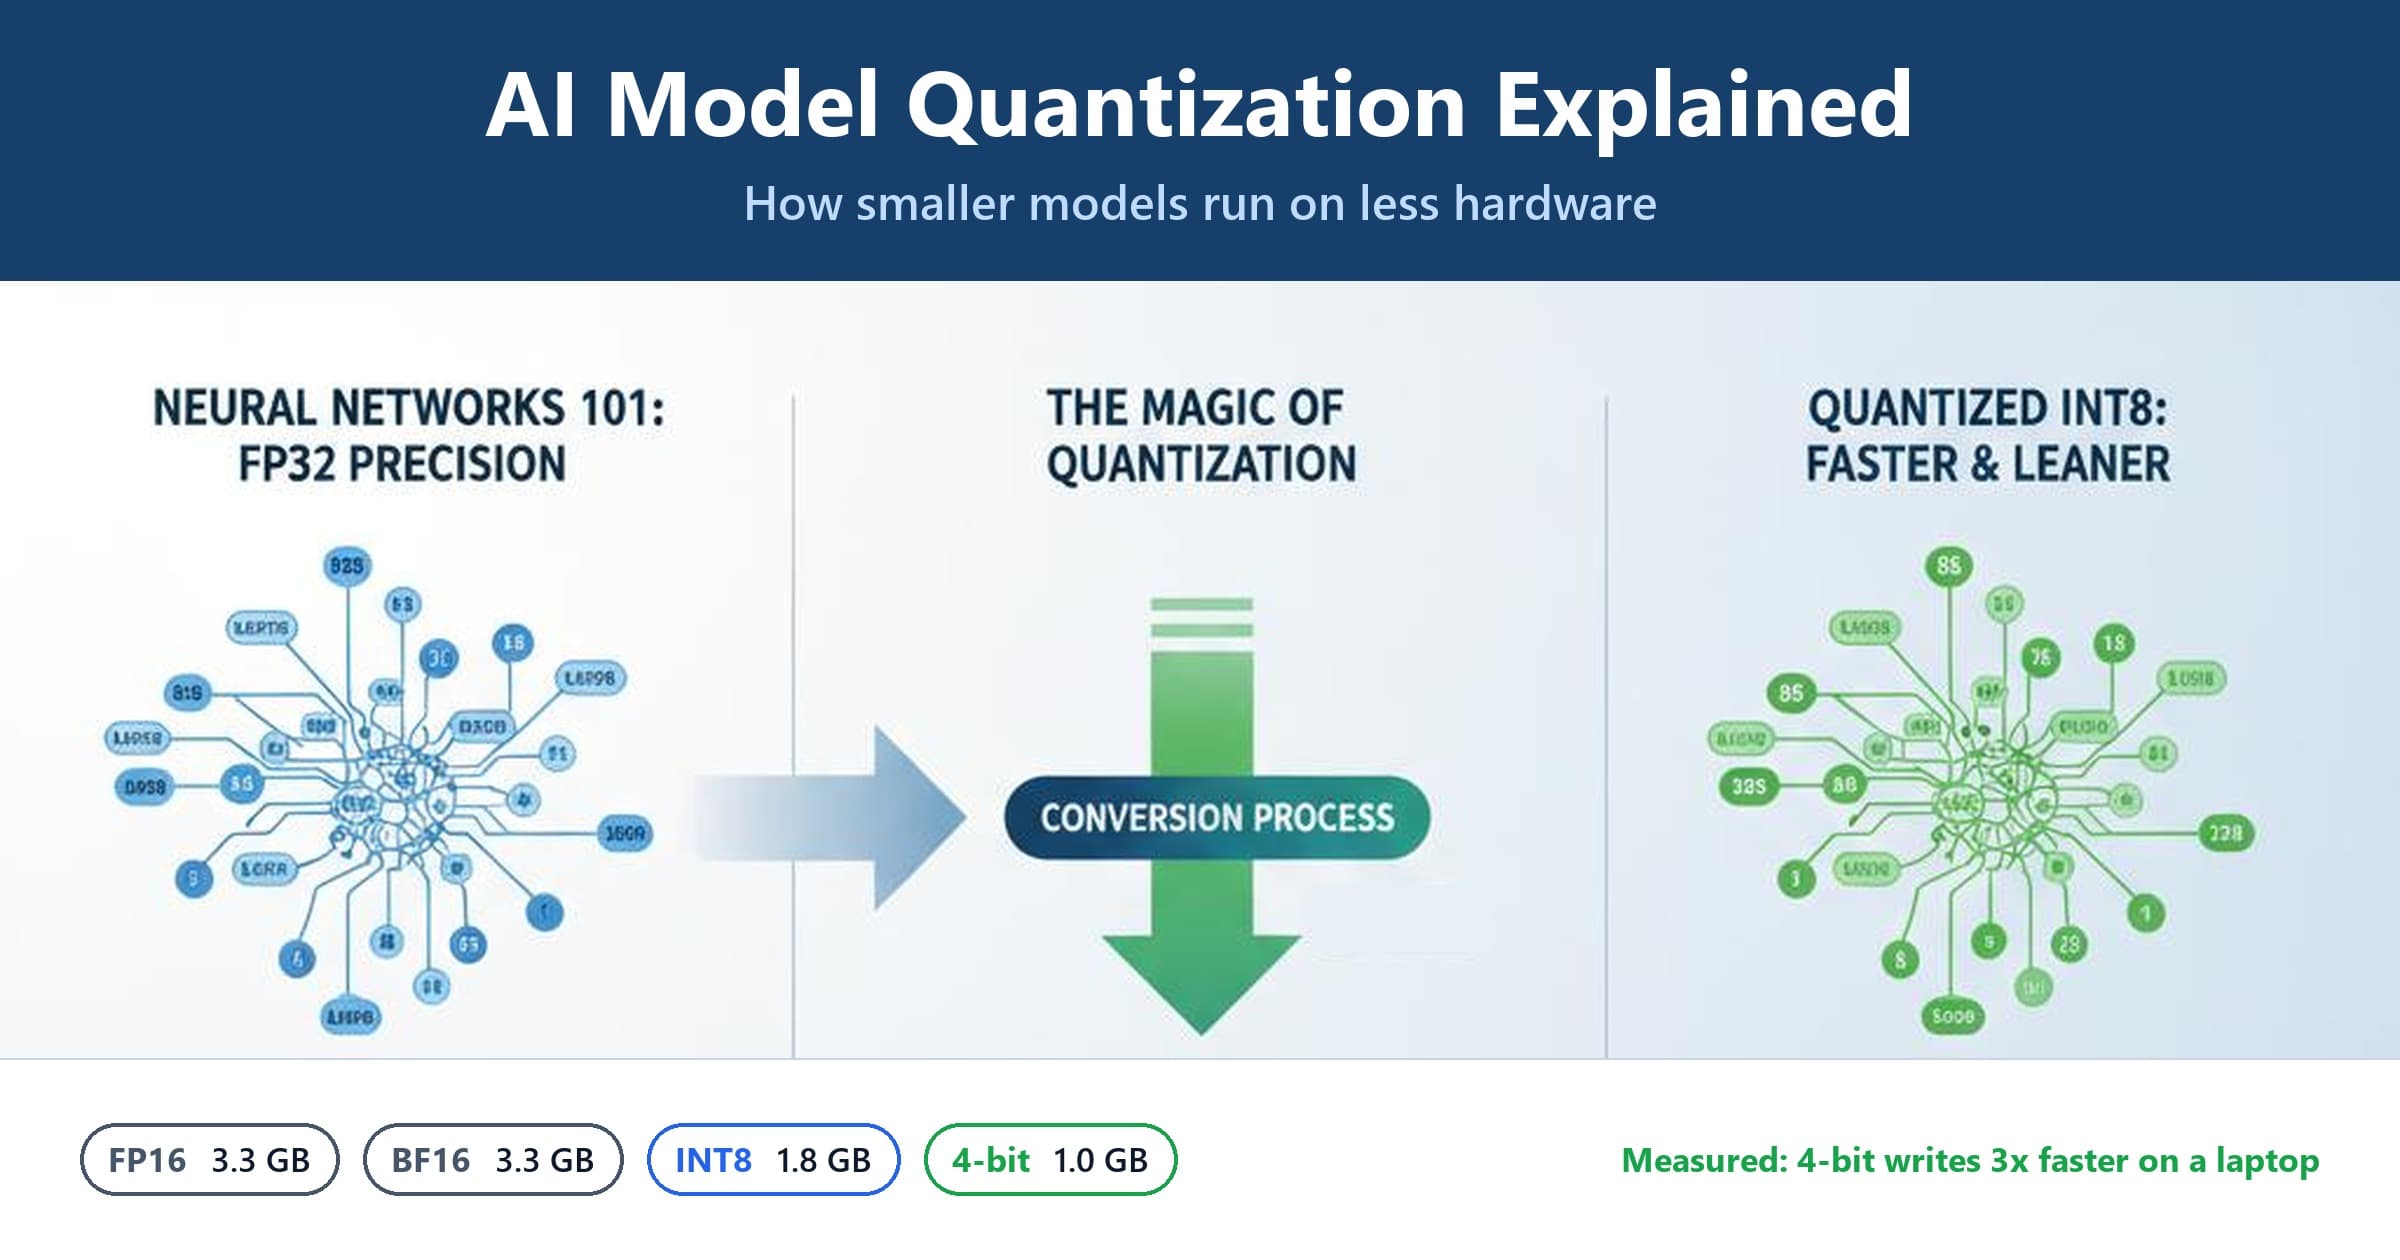
FP16, BF16, INT8 and 4-bit compared with a real laptop experiment: how much memory each format saves, how much faster it runs, and what it does to answers.
16m read
Read