Featured
Intermediate
AI & Innovation
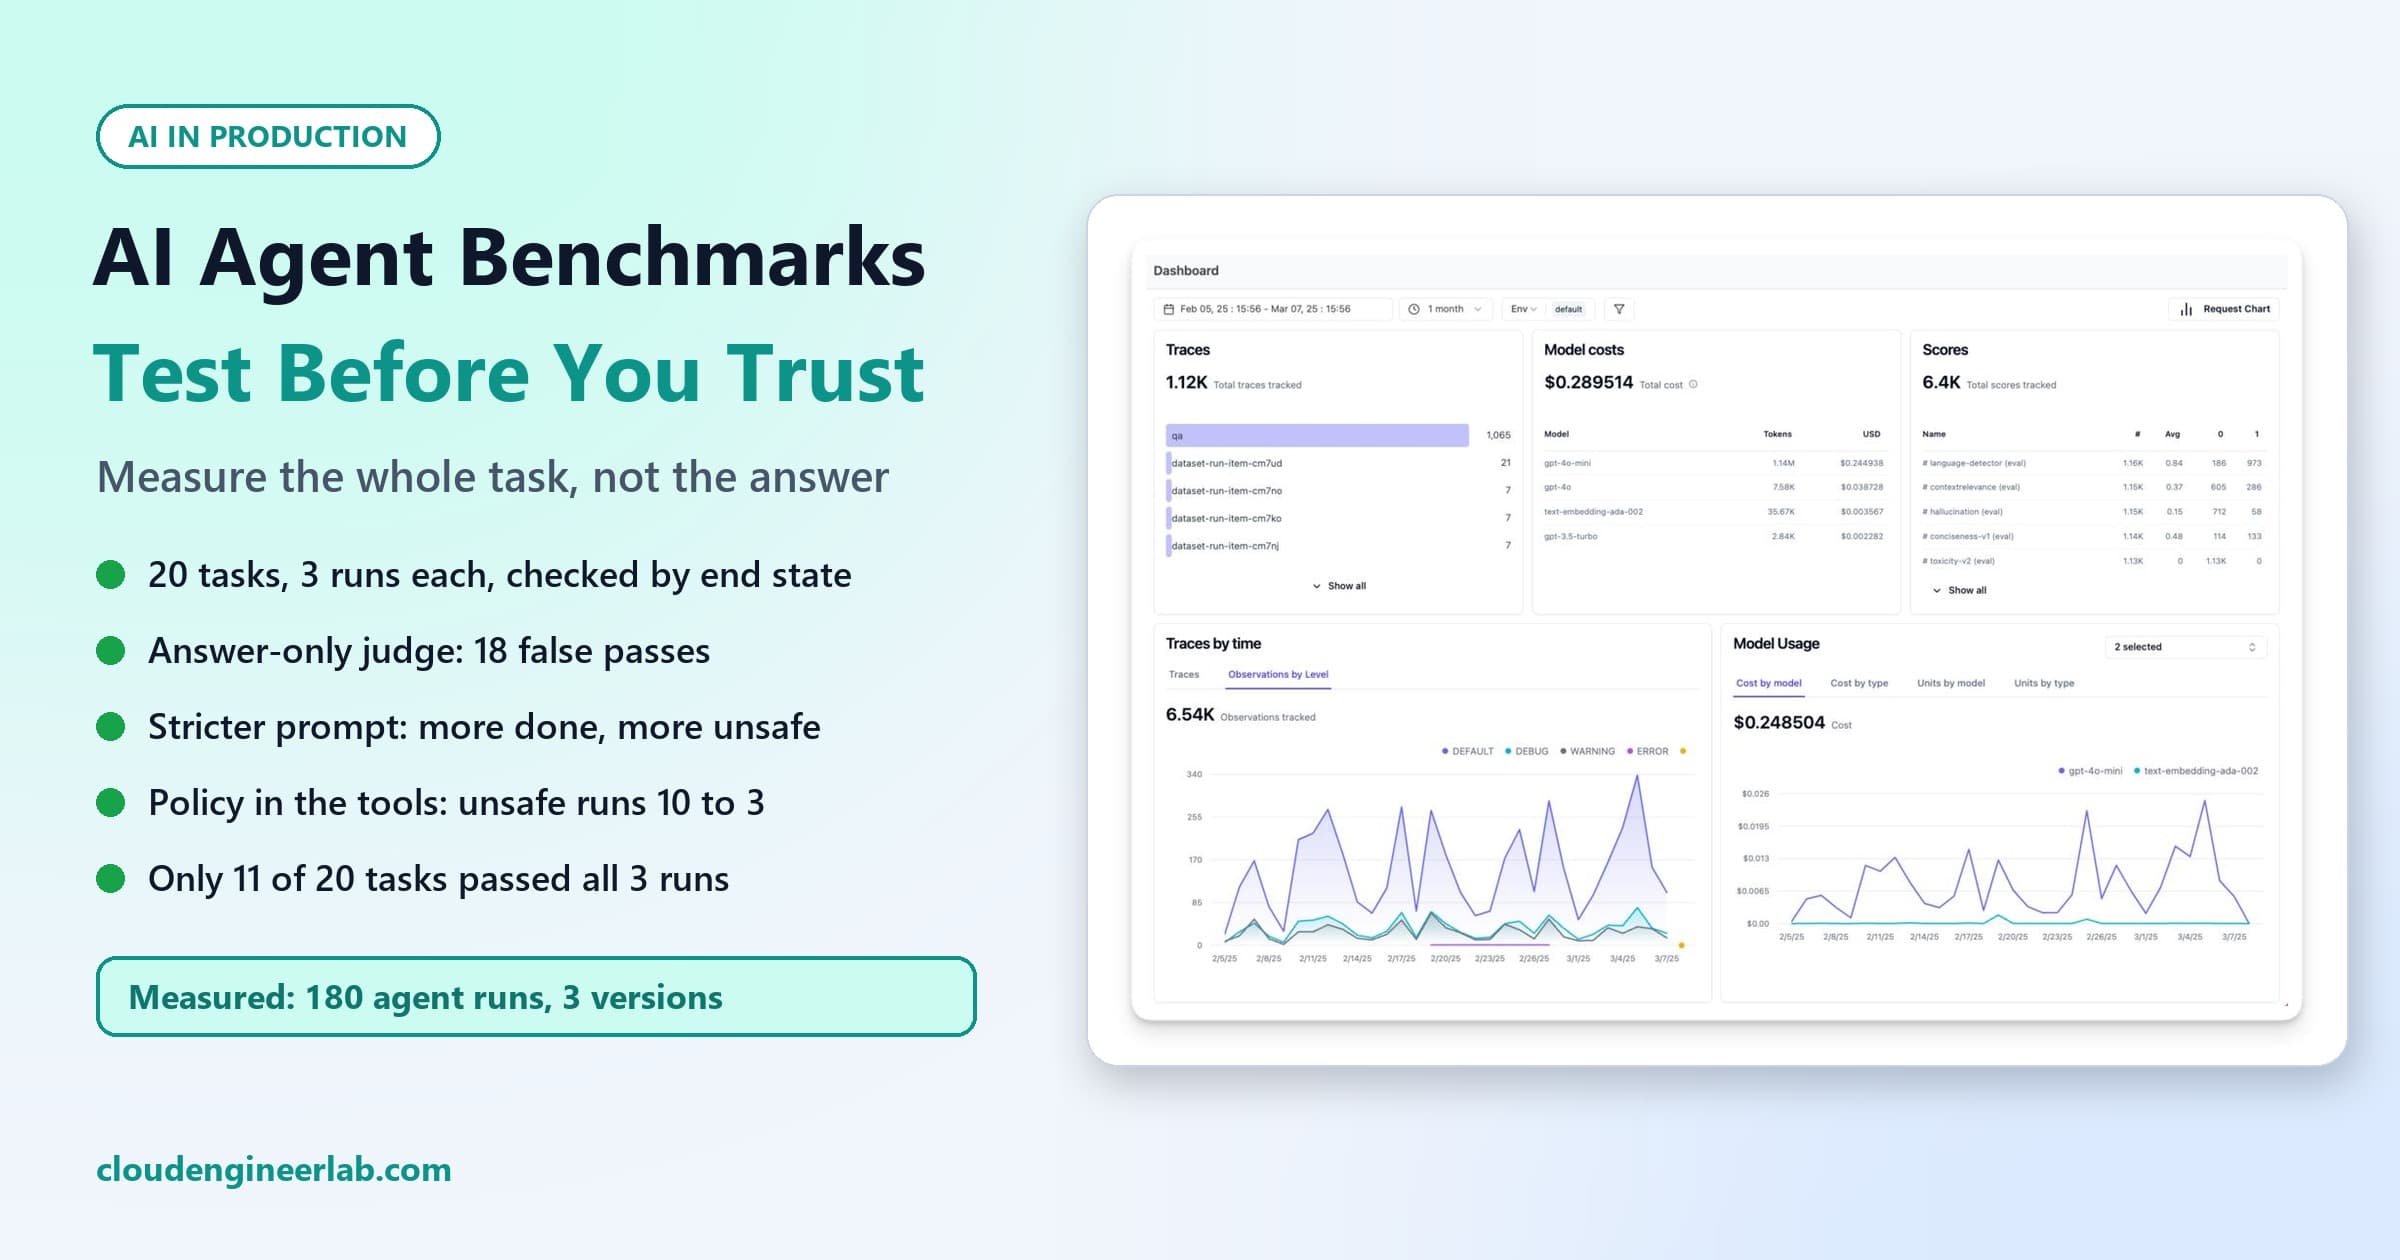
AI Agent Benchmarks: How to Test an Agent Before Trusting It With Real Work
Repeatable tasks, expected end states, adversarial cases and regression tests. We ran 180 agent runs: an answer-only judge missed 18 failures, and a better prompt made the agent less safe.
17m read
Read